Overview
The Embodied Artificial Intelligence (Embodied AI) Labs are a core experiential component of the CSE 494/598 Topic: Intelligent and Safe Cyber-Physical Systems (ISCPS) course at Arizona State University.
Students design, implement, and evaluate intelligent agents that interact with the physical world, with a strong emphasis on:
- safety and robustness,
- timing and physical consequences,
- authentication and authorization,
- coordination under communication failures,
- interpretability of decisions,
- and principled reasoning in environments where cyber-physical systems operate.
Lab sequence
The four labs progress from language-based reasoning to visual decision-making, action authorization, and coordination among multiple embodied agents:
| Lab | Agent | System and safety focus |
|---|---|---|
| A: Agentic Driving Coach | LLM agent | Logical time, inference deadlines, deterministic fallback, and stopping outcomes |
| B: Embodied Agent Authentication | VLM agent | Sensor impersonation, authenticated inputs, and independent post-run evaluation |
| C: Safe Agent Actuation | VLA agent (recorded) | Recorded pi0-FAST response inspection, synthetic ALOHA fixtures, and SST-backed EXECUTE/HOLD enforcement |
| D: Safe Multi-Embodied Agents | Multiple vehicle agents | Intersection reservations, delayed or lost messages, and the tradeoff between exclusion and progress |
Each project combines a concrete embodied-agent system with reproducible experiments. Students connect model behavior and computer-system mechanisms to observable outcomes rather than evaluating the AI model in isolation.
Start a lab
Open the page for your assigned project, then follow the repository’s README.md
for setup and ASSIGNMENT.md for graded tasks and deliverables. The public
repositories are course templates; students complete their work in private
group repositories created from those templates.
Labs A and B use live models, with ASU Sol as the primary platform. Lab C’s graded experiments use CPU compute, a committed model capture, and synthetic fixtures. Lab D runs entirely on a CPU using native Ubuntu, native macOS, or Sol; it requires no model download or GPU. See Lab Format & Logistics for the shared workflow and each repository for its specific setup.
Copyright © Hokeun Kim 2026–2026
Lab A: Agentic Driving Coach
Agent type: Large Language Model (LLM) agent
Goal
Place a small local LLM in the control loop of a simulated car approaching a stop sign. The coach reasons about the situation and produces driving guidance or emergency actuation while the system tracks both logical time and real inference latency.
The central question is not only whether an LLM response is sensible, but also whether it arrives in time to affect the physical outcome. Late, malformed, or unsafe responses trigger a deterministic fallback.
You compare live llama3.2:1b and llama3.2:3b models with deterministic rule
and replay runs. Recorded short-deadline traces let you examine missed deadlines
and late responses separately from your machine’s live inference performance.
System topology
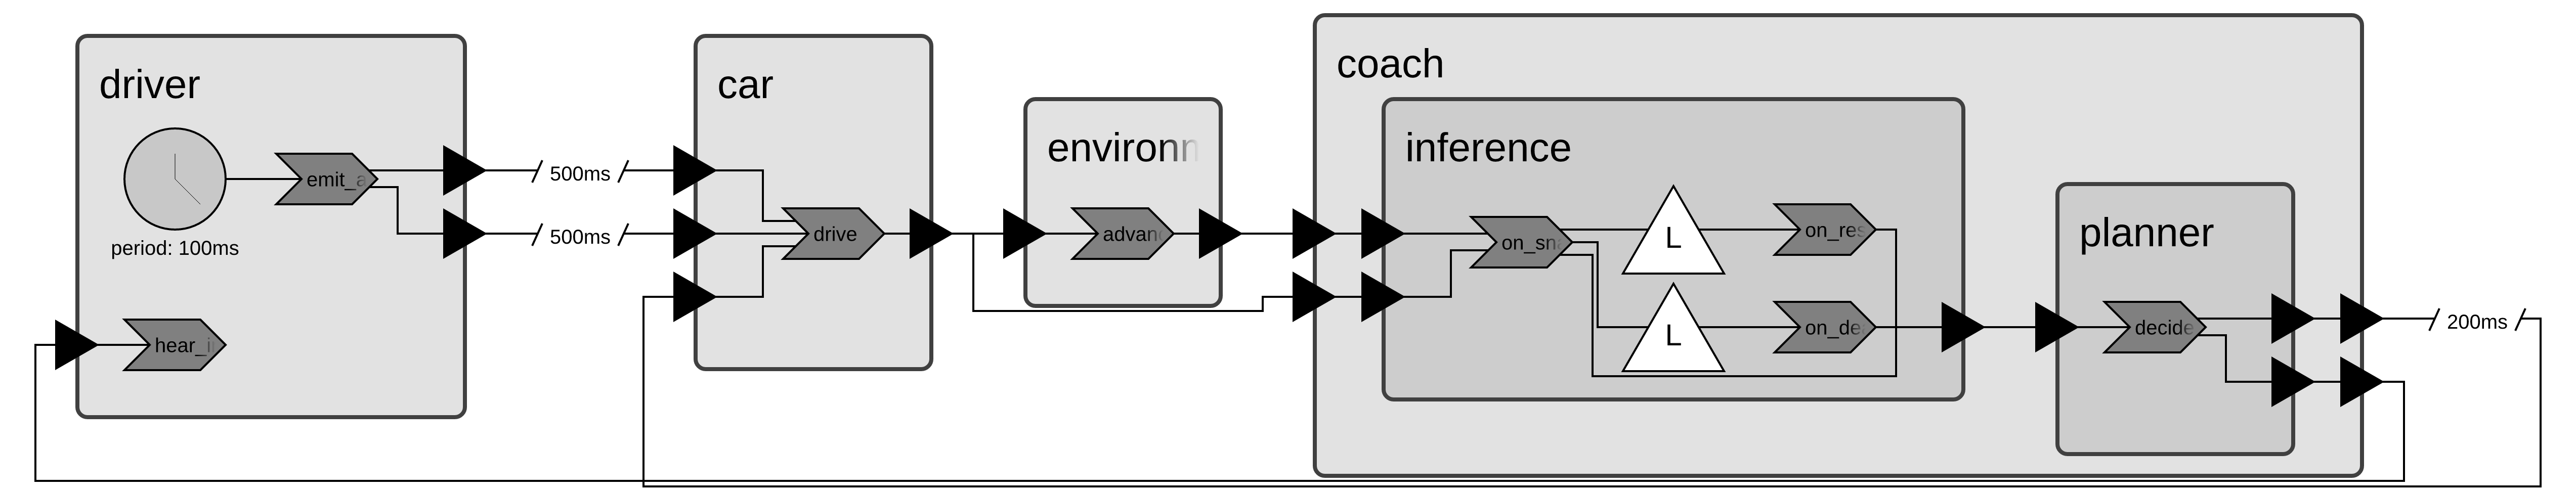
The driver, car, environment, hierarchical coach, inference deadline race, and planner form a closed loop. Driver commands cross 500 ms logical delays, while coach emergency actuation returns over a 200 ms delay. Click the diagram for the full-size topology from the project repository.
Focus
- LLM reasoning inside a cyber-physical system’s control loop
- Xronos reactors, logical time, wall-clock lag, and delayed connections
- Inference deadlines, response validation, and deterministic fallback
- Reproducible comparison of model latency, output quality, and stopping outcome
What you will do
- Work through five Xronos examples, including the difference between an after-the-fact deadline check and a fallback scheduled independently of model completion.
- Run deterministic rule and replay baselines, predict the effects of small reactor edits, and compare the predictions with recorded behavior.
- Compare live local LLMs under identical conditions and examine recorded deadline-stress replays, clearly identifying each source of results.
- Analyze how driver behavior, model timing, and fallback decisions change the simulated car’s physical outcome.
- For the CSE 598 extension, choose a speed-change scenario, generated driver behavior, a deadline sweep, or a live-input reactor and compare it with a controlled baseline.
Learning outcomes
By the end of this lab, you should be able to:
- distinguish logical time from wall-clock inference time, lag, and slack;
- measure latency, deadline misses, and malformed model responses;
- explain why deterministic fallback is needed in an agentic control loop; and
- connect software timing and model behavior to a physical stopping result.
Project repository
Use the public embodied-ai-lab/agentic-driving-coach template to create your group’s private repository. ASU Sol is the primary platform: timing examples and deterministic baselines use CPU compute, while the documented live-model workflow uses a GPU allocation.
Lab B: Embodied Agent Authentication
Agent type: Vision-Language Model (VLM) agent
Goal
Study source authentication in the control loop of a simulated warehouse cart.
A live qwen2.5vl:3b VLM receives a camera image, a natural-language mission,
and a reported obstacle distance before selecting STOP or PROCEED.
You first impersonate a ROS 2 publisher and observe how untrusted sensor data can induce an unsafe decision. You then use the Secure Swarm Toolkit (SST) to authenticate the legitimate distance and camera sources before their data reaches the VLM agent.
The cart executes the schema-valid model action unchanged. Only after ROS stops does a separate evaluator use ground truth to judge the recorded execution. Neither the VLM nor the cart receives ground truth.
System data flow
The runtime decision and execution logs feed an independent post-run evaluator. Ground truth reaches only that evaluator, which never feeds back into the control loop. Adapted from the project’s documented data flow.
Focus
- VLM-based perception and decision-making for an embodied agent
- ROS 2 publisher impersonation and malicious sensor inputs
- Source authentication and protected delivery with SST
- Separation of source identity, sensor truth, model decisions, and post-run outcomes
What you will do
- Run a trusted baseline and inspect the ROS 2 graph.
- Implement a replacement distance publisher and trace false input through the VLM decision, cart execution, and independently evaluated outcome.
- Repeat the attack at seven reported distances with three trials each, keeping other inputs fixed and distinguishing invalid runs from model variability.
- Implement the SST channels and demonstrate both authenticated legitimate inputs and rejection of an unregistered replacement source before inference.
- For the CSE 598 extension, compare a legitimate red-camera baseline, a malicious green-image replacement, and the SST-protected case.
Missing, stale, invalid, or unauthenticated inputs cause a fail-closed STOP.
Successful source authentication establishes who sent protected data; it does
not establish that the data is physically true or that the model’s action is safe.
Learning outcomes
By the end of this project lab, you should be able to:
- explain how unauthenticated sensor publishers can influence a VLM agent;
- distinguish the VLM’s selected action from the independently evaluated physical outcome;
- authenticate legitimate physical data sources with SST; and
- evaluate both the protection gained and the limits of source authentication.
Project repository
Use the public embodied-ai-lab/embodied-agent-auth template to create your group’s private repository. The primary workflow runs ROS 2, SST, and live VLM inference in an ASU Sol GPU allocation. Complete the assigned implementation and rebuild the ROS package before running its graded attack or protected modes.
Lab C: Safe Agent Actuation
Agent type: Vision-Language-Action (VLA) agent — recorded response and controlled action experiments
Goal
Study how motion analysis, context-based authorization, and actuator enforcement work together for VLA actions. First, inspect a genuine recorded pi0-FAST DROID response and its FAST decoding evidence. Then use explicitly synthetic ALOHA action fixtures to implement and evaluate the enforcement path.
These are two separate data sources: the recorded DROID response is inspected but never executed or converted into ALOHA commands. The graded motion experiments use 14-dimensional ALOHA fixtures and a controlled current state.
The monitor validates a fixture, measures its normalized motion, and compares
the score with a risk threshold. High-risk actions require context-based
authorization and protected delivery through the
Secure Swarm Toolkit (SST). A recording actuator
harness validates the input and records EXECUTE or HOLD.
Safety pipeline
Part 1 inspects a committed model capture. Parts 2–5 analyze synthetic fixtures and exercise actuator enforcement with real SST. The recording harness measures forwarding and rejection, not robot dynamics or task success. Adapted from the project architecture.
Focus
- VLA response provenance, token availability, and FAST decoding evidence
- Normalized motion analysis on controlled joint and gripper commands
- Context-based authorization and protected delivery for high-risk actions
- Actuator enforcement, invalid-input rejection, and session-key reuse
What you will do
- Inspect the genuine pi0-FAST response, its metadata, checksum, returned shape, and reported token availability. The pinned standard response does not expose raw token IDs.
- Implement motion analysis using synthetic ALOHA fixtures, the current state, physical ranges, and the risk threshold.
- Demonstrate an authorized high-risk action, a denied context, and rejection of an unauthenticated actuator bypass using real SST.
- Compare thresholds on the same fixture/context cases. Report classification, authorization activity, key requests and reuse, and measured Monitor-to-actuator latency.
- For the CSE 598 extension, measure how session-key validity affects reuse and the security window after the context changes.
Learning outcomes
By the end of this lab, you should be able to:
- distinguish a captured model response from synthetic action fixtures;
- explain why motion is assessed in decoded physical space rather than from token identifiers;
- enforce authentication and authorization at the actuator boundary; and
- distinguish motion classification, policy authorization, and observed enforcement from a claim of physical safety.
The graded harness does not simulate robot dynamics or control a real robot. All graded parts run on CPU compute with the committed capture; no GPU, model download, or live model server is required.
Project repository
Use the public embodied-ai-lab/safe-agent-actuation template to create your group’s private repository. Follow its ASU Sol CPU workflow and complete the student TODOs before running the full experiment set. Offline diagnostic authorizers are development aids; graded authorization results require real SST.
Lab D: Safe Multi-Embodied Agents
Agent type: Multiple embodied agents — three connected vehicles and a roadside coordinator
Goal
Coordinate three simulated vehicles approaching a shared intersection from different directions. A Roadside Unit (RSU) acts as the intersection’s coordinator and grants permission to enter, while SUMO simulates the motion and a Python message network introduces delay, loss, and duplication.
The central question is when the next car may enter if the previous car has not confirmed that it is clear. A timer expiring is not evidence that the physical intersection is empty. You compare independent driving, a timer-based lease policy, and a reservation protocol that waits for a matching release.
Coordination architecture
RSU stands for Roadside Unit: the simulated roadside infrastructure agent that queues vehicles’ crossing requests, issues grants, and tracks the active reservation. It relies on delivered messages and its reservation state; it cannot see the road. Each car observes its own state. The evaluation monitor sees all vehicle positions for metrics only and never influences a decision. Adapted from the project’s coordination protocol.
Focus
- Exclusive reservations for a shared physical conflict zone
- Grant identity, request IDs, reservation epochs, and entry deadlines
- Retransmission and duplicate handling under communication failures
- Separate measures of exclusion violations, collisions, waiting, and completion
What you will do
- Run the supplied
independentandleasebaselines and inspect their browser replays, event logs, and occupancy timelines. - Complete
choose_request,grant_is_usable, andrelease_matchesincavlab/policies.pyto implement therobustprotocol checks. - Compare the three policies across
nominal,slow_car,delayed_grant, andlossy: twelve controlled runs in total. - Trace a failure from message timing to entry decisions and vehicle motion. Explain why permanent loss of a release can prevent progress even while the coordinator preserves the reservation.
- For the CSE 598 extension, vary the grant’s start window under a fixed message delay and analyze expired grants, waiting, and completion.
Learning outcomes
By the end of this lab, you should be able to:
- explain why an entry deadline does not end an occupied reservation;
- validate grants and releases while rejecting stale or mismatched messages;
- distinguish a conservative exclusion violation from a geometric collision;
- assess progress together with safety observations; and
- state the assumptions behind the protocol, including truthful clearance reports, trusted message identities, and a shared simulation clock.
Message identities are trusted simulation labels, not cryptographic
authentication. The default planner is a replaceable rule-based component;
live model inference is outside the graded workflow. All experiments run on a
CPU, and each run produces a self-contained replay.html that opens directly
in a browser.
Project repository
Use the public embodied-ai-lab/safe-multi-embodied-agents template to create your group’s private repository. Choose native Ubuntu, native macOS, or ASU Sol with Apptainer; no GPU or model download is required.
Lab Format & Logistics
Format
The Embodied AI Labs balance concepts, implementation, experimentation, and reflection.
Each repository provides a student-facing README.md for setup and commands and
an ASSIGNMENT.md for the required experiments, questions, deliverables, and
rubric.
-
Project setup Create a private group repository from the assigned public template and prepare the documented environment.
-
Implementation and checks Complete the assigned components and use the repository’s checks to validate the system incrementally.
-
Experimentation and evaluation Run the required scenarios, collect result artifacts, and compare timing, security, safety, or policy behavior.
-
Discussion and reflection Explain failure cases, safety boundaries, physical outcomes, and the limits of the evaluation.
Deliverables
The canonical deliverables and grading rubric are in the assigned repository’s
ASSIGNMENT.md. Typical deliverables include:
- concise written answers and result tables,
- completed source code and configuration,
- required experiment artifacts, and
- a submission archive generated by the repository’s submission script.
Logistics
The public repositories are templates. Create a private repository for your group, add only your project partners, and do not publish course work in a public repository.
Choose the environment documented for your assigned lab:
| Lab | Primary workflow | Model or simulation use |
|---|---|---|
| A: Agentic Driving Coach | ASU Sol; personal Linux is an alternative | CPU timing and replay exercises; GPU allocation for the documented live LLM runs |
| B: Embodied Agent Authentication | ASU Sol | Live VLM inference with ROS 2 and SST in a GPU allocation |
| C: Safe Agent Actuation | ASU Sol CPU allocation | Committed model capture, synthetic fixtures, real SST, and a recording actuator harness |
| D: Safe Multi-Embodied Agents | Native Ubuntu, native macOS, or ASU Sol CPU allocation | SUMO simulation and a message network; no live model or GPU |
Follow the allocation, container, and cleanup instructions for your specific project. Do not run compute-intensive work on a Sol login node. Environment checks confirm that tools are ready; they do not establish that unfinished student implementations are correct or that graded experiments are valid.
Each assignment has common CSE 494/598 work and an additional CSE 598 extension. Include the extension in the same group submission archive, using the repository’s section-specific packaging command where provided. Keep recorded model output, synthetic fixtures, live measurements, and offline diagnostics clearly identified in your answers.
The course LMS remains authoritative for deadlines, group assignments, and submission. Before uploading, inspect the generated archive and confirm that it contains the current code, answers, and required results.
Contributors
The Embodied AI Labs for CSE 494/598 Topic: Intelligent and Safe Cyber-Physical Systems at Arizona State University are being developed and maintained by:
- Hokeun Kim
- Marten Lohstroh
Additional contributors may be added as the lab sequence evolves.